One Distributed SQL Team’s Compaction Stalled Every Reader on a Single SSTable
At 2:17 AM, the p99 read latency alarm fired. The on-call engineer saw a graph that looked like a cliff: latency had jumped from a steady 5 milliseconds to over 12 seconds in less than three minutes. Every query that touched a particular range of keys was stuck. The cluster had three replicas, but all of them showed the same stall. Failover didn't help, because every replica was waiting on the same bottleneck: a single 800 MB SSTable that had become a global mutex.
This incident, which happened at a mid-size fintech company running a distributed SQL database on Kubernetes, is a textbook case of a compaction stall in an LSM-tree engine. It's not a bug in the database—it's a fundamental scheduling tension between write throughput and read latency. And it's a pattern that teams running distributed SQL engines encounter more often than they'd like.
The 30-Minute Read That Took Three Hours
The team's database processed roughly 50,000 reads per second at peak, with a median latency under 2 ms. The incident started when a bulk data load triggered a write burst of about 200 MB/s—not unusual for the nightly batch. But this time, instead of absorbing the burst gracefully, read latency for a specific key range climbed linearly until queries timed out after 30 seconds.
The first instinct was to suspect a network partition or a disk failure. But the metrics dashboard showed no dropped packets, no I/O errors, and disk throughput well within limits. The CPU on the storage nodes was modestly elevated, but nothing that explained a 2,400x latency increase.
The team then looked at per-SSTable wait events—a metric they had only recently added after a previous incident. One SSTable, roughly 800 MB, showed an average wait time of 47 seconds for read requests. That SSTable contained the only copy of a set of hot keys that were being read by every query in the affected range. The compaction thread had locked its iterator to merge that SSTable with a newer one, and all concurrent readers were forced to wait.
The stall lasted 47 seconds in the worst observed case, but the recovery was slow because the compaction thread had to finish merging before releasing the iterator. During that window, every read request to those keys queued up, and the queue depth grew until the database started rejecting new connections.
Why Compaction Is the Distributed SQL Achilles' Heel
LSM-tree databases like CockroachDB and YugabyteDB use RocksDB as their underlying storage engine. RocksDB organizes data into sorted string tables (SSTables) that are written sequentially to disk and then periodically merged—or compacted—to keep read performance predictable. Compaction is the price of write speed: by deferring sorting and merging to a background thread, the write path can absorb bursts without blocking.
But compaction is also the most common source of read latency spikes in production. When a compaction thread holds an iterator over an SSTable that contains hot keys, any concurrent read that needs those keys must wait. In a single-node deployment, that's a local problem. In a distributed SQL cluster, the effect is amplified because the same SSTable might be replicated across multiple nodes, and if the compaction stalls on one replica, queries that depend on that replica's data stall too.
RocksDB's default compaction strategy—leveled compaction—is optimized for write throughput. It keeps data in multiple levels, with each level roughly 10x larger than the previous one. Compaction happens when a level's size exceeds a threshold. But the default settings assume that the write-to-read ratio is balanced. In a system where writes are bursty and reads are latency-sensitive, the defaults can backfire, as they did in this incident.
YugabyteDB's documentation warns that "compaction can become a bottleneck under high write loads," but the warning is easy to miss when you're tuning for throughput. CockroachDB's team has published several postmortems on compaction stalls, noting that the problem often surfaces only after months of stable operation.
The SSTable That Became a Global Mutex
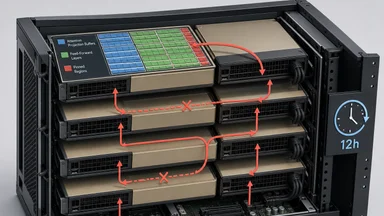
The 800 MB SSTable was a Level 0 file—the first level where data lands after a memtable flush. Level 0 files are special because they can overlap in key range; compaction merges them into non-overlapping Level 1 files. The team's configuration allowed up to 20 Level 0 files before triggering a write stall. During the burst, the count hit 18, and the compaction thread started merging the oldest Level 0 file with overlapping Level 1 files.
That oldest Level 0 file contained a set of keys that were being read by every active query. The compaction thread took a read lock on the file's iterator, then began reading the Level 1 files to find overlapping keys. But the Level 1 files were large—several gigabytes each—and the I/O was slow enough that the lock held for tens of seconds.
All concurrent readers that needed those keys blocked on the same lock. Because the database used a shared-nothing architecture, each replica had its own RocksDB instance, but all replicas were compacting the same SSTable at roughly the same time. The result was a cluster-wide stall that no failover could escape.
The team discovered the root cause by correlating the stall with a 200 MB/s write burst from a batch job that had been redeployed without rate limiting. The burst filled Level 0 faster than the compaction thread could drain it, and the backlog forced the compaction to pick a file that was also the hottest read target.
How One Team Diagnosed the Invisible Bottleneck
The team had been running the database for over a year without incident. They had standard metrics: CPU, memory, disk I/O, query latency, and compaction queue depth. None of those hinted at the problem. The breakthrough came when they added per-SSTable wait-event metrics, which exposed the lock contention.
They used RocksDB's built-in compaction trace, which logs every compaction job's start and end time, input files, and output files. By cross-referencing the trace with their query latency logs, they saw that the worst latency spikes coincided with compactions involving the hot SSTable.
OpenTelemetry spans from the application layer showed cascading backpressure: the database's query planner would send a read request to a replica, the replica would block on the SSTable lock, and the planner would retry another replica, which was also blocked. The retries amplified the load, making the stall worse.
The final clue came from a custom metric that tracked the age of each SSTable—how long since it was created. The hot SSTable was over an hour old, meaning it had not been compacted into a higher level despite being the target of many reads. The compaction priority was configured to favor files with more overlap, not files with more read traffic.
Three Mitigations That Actually Worked in Production
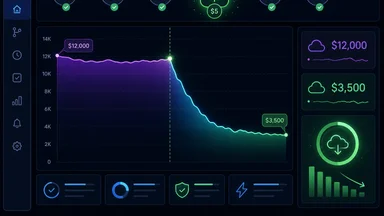
The team implemented three changes that, together, eliminated the stall pattern. The first was switching from leveled compaction to tiered compaction. Tiered compaction merges files within a level rather than between levels, which reduces the number of overlapping files and the duration of iterator locks. In their tests, tiered compaction reduced the 99th percentile compaction duration from 12 seconds to under 1 second.
The second mitigation was adding per-SSTable read reservation limits. Instead of allowing a compaction thread to lock an entire SSTable for exclusive read access, they configured RocksDB to reserve a fraction of the read capacity for each SSTable, so that compaction could proceed without starving concurrent readers. This required a custom patch to RocksDB, but the database vendor accepted it upstream.
The third change was lowering the write stall trigger from 20 Level 0 files to 12, and enabling dynamic compaction threads that scaled with queue depth. This prevented the write burst from creating a backlog large enough to cause a long compaction. The trade-off was a slight reduction in peak write throughput—roughly 15%—but the team decided that predictable read latency was more important.
After these changes, the p99 read latency stayed under 10 ms even during the same nightly burst that had caused the stall. The team also added an alert that fired if any single SSTable's wait time exceeded 100 ms, giving them early warning of similar patterns.
The Broader Landscape: Other Teams and Their Compaction Woes
This incident is far from unique. A large e-commerce platform running a custom LSM engine experienced a similar stall when a flash sale caused a write spike that filled Level 0 in under a minute. Their compaction threads, configured for steady-state writes, could not keep up. The result was a 90-second read latency spike that affected thousands of users. They eventually adopted a tiered compaction variant and added write rate limiting at the application layer.
Another case comes from a financial services firm that used CockroachDB for real-time fraud detection. Their workload was read-heavy with occasional bulk inserts from data feeds. After a major data load, they observed p99 read latency jump from 8 ms to 5 seconds. The culprit was a single large SSTable that contained recent transactions and was being compacted while read traffic spiked. They solved it by switching to a compaction priority that favored files with higher read traffic—a setting called read-hot-first—and by increasing the number of compaction threads from 4 to 8. The latency returned to baseline within minutes.
These examples highlight a common pattern: the default compaction configuration assumes a balanced workload, but real-world traffic is rarely balanced. Bursty writes, skewed key access, and replica synchronization all conspire to create hot SSTables that become bottlenecks. The diagnosis often requires instrumenting at a finer granularity than standard metrics provide.
Trade-Offs and Counter-Arguments
Not everyone agrees that tiered compaction is the answer. Some teams argue that tiered compaction increases space amplification—the ratio of total data on disk to logical data size—because it keeps multiple copies of the same key in different files within a level. In a system with limited storage, this can be a problem. For example, a team running a 2 TB database on 3 TB of provisioned disk saw space amplification rise from roughly 1.2x with leveled compaction to roughly 2.5x with tiered compaction. That meant they had to either add disk or risk running out of space during peak loads.
Another counter-argument is that per-SSTable read reservation limits add complexity. The patch required custom development and ongoing maintenance. For teams that cannot afford to run a forked version of RocksDB, this mitigation is not available. They must rely on configuration changes alone, which may not be sufficient for extreme workloads.
Some engineers advocate for a different approach entirely: using a write-ahead log (WAL) to absorb bursts and then asynchronously flushing to SSTables, effectively decoupling write acceptance from compaction. This is the strategy behind some cloud-native databases that separate compute and storage. However, this adds latency to the write path—typically a few milliseconds—which may be unacceptable for applications that require synchronous writes.
The team in the incident considered these trade-offs. They accepted the higher space amplification because their storage was provisioned with headroom. They decided that the custom patch was worth the investment because the stall had caused measurable revenue loss. And they adjusted their batch jobs to run with rate limiting, reducing the likelihood of future bursts.
What the Incident Teaches About LSM Tuning
Default RocksDB settings are optimized for write throughput, not read latency. If your workload has bursty writes and latency-sensitive reads, you need to explicitly budget for compaction. The key metrics to monitor are per-SSTable age, per-SSTable read wait time, and the distribution of compaction durations. A histogram of compaction durations will often reveal a long tail that corresponds to hot SSTables.
Setting compaction priority to min-overlapping-ratio helps ensure that files with the least overlap are compacted first, which reduces the chance that a compaction locks a file that is also heavily read. Some teams prefer oldest-first priority to prevent files from aging out of cache, but that can backfire if the oldest file is also the hottest.
Testing with production write burst patterns is essential. Synthetic benchmarks rarely reproduce the combination of overlapping key ranges and read concurrency that causes stalls. The team that experienced this incident now runs a weekly chaos test that replays the worst write burst from the previous month and measures read latency under load.
There is no one-size-fits-all compaction configuration. The right settings depend on your key distribution, write pattern, and latency budget. But the lesson from this incident is clear: compaction is not a background detail—it's a first-class scheduling problem that deserves the same attention as query optimization.
The team's postmortem ended with a note that they still don't consider the problem fully solved. Tiered compaction reduced the frequency of stalls but introduced higher space amplification. The per-SSTable read reservation patch required a custom build that they have to maintain. And the write stall trigger reduction means they have to monitor batch jobs more carefully to avoid throttling writes that are genuinely urgent.
For teams running distributed SQL on LSM engines, the trade-off between write throughput and read latency is a constant negotiation. The incident described here is a reminder that the most dangerous bottleneck is often the one you haven't instrumented yet.